Stochastic foundations of machine learning · Iowa State University
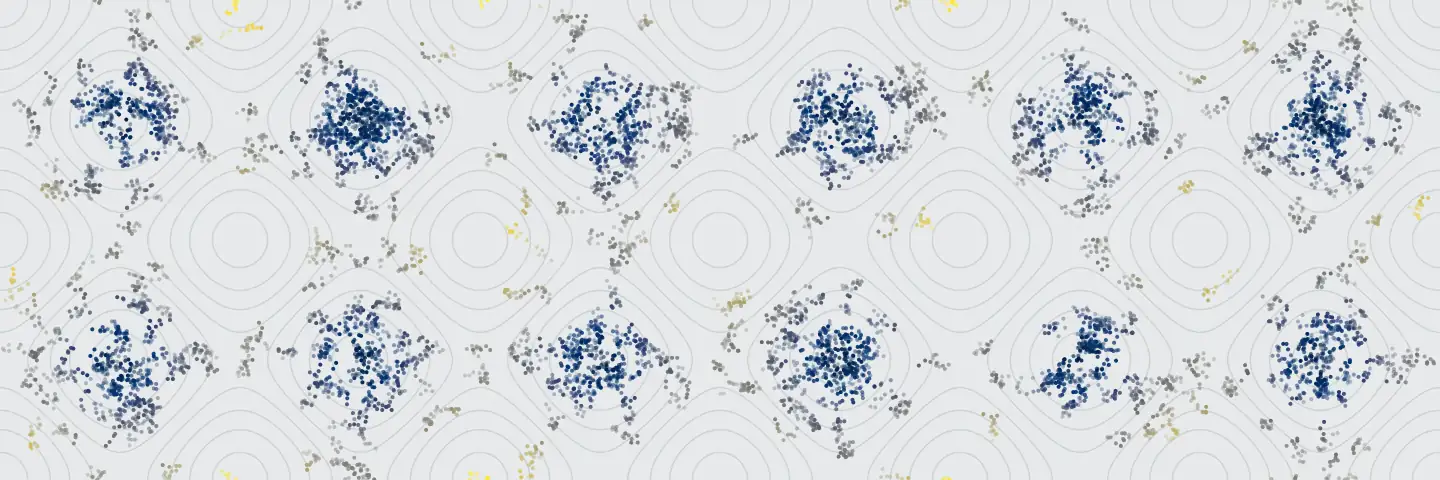
t = 2.0N = 648β = 2.0
Fig. 1
Object
overdamped Langevin
Potential
V = cos x + cos y
Integrator
Euler–Maruyama, h = 0.004
Checked
TV 1.0×10⁻³ vs Gibbs
−2+2
Color: potential V
I’m an undergraduate researcher at Iowa State University working on reliable
machine learning and scientific computing. I build Python simulations and
GPU experiments to measure when methods fail, explain why, and test ways to
improve them. My projects span LLM serving, statistical forecasting, and
numerical algorithms.
I work on the stochastic foundations of machine learning: the theory of
stochastic differential equations, applied to the algorithms that now
generate and sample. A diffusion model is a reverse-time SDE, stochastic
gradient descent and its Langevin variants are diffusions in a rough loss
landscape, and a PAC-Bayes bound is the Donsker–Varadhan formula applied to a
posterior over hypotheses. Three questions occupy me: what the discretization
of a Langevin sampler actually costs, how to estimate probabilities too small
for direct simulation to reach, and whether a PDE solver with a network inside
it will hold together when you iterate it. Underneath all three is the same
question, which is what can be proved about the objects practitioners already
use: rates, stability, and error bounds in place of heuristics. A second set
of projects, in computer science, carries the same habits into the systems
that run large language models: whether a burst of agent traffic can tip a
serving engine into a self-sustaining slow state, how to calibrate a forecast
when its feedback arrives early but one-sided, and when restarting a stalled
agent beats waiting. Everything moving on this page is one of the stochastic
objects, running live and graded against a closed-form answer.
The band above is running in your browser from a fixed seed. It integrates
dXt=−∇V(Xt)dt+2β−1dWt
on the torus. Annealed Langevin sampling runs this same dynamics at each noise
level, and it is the continuous-time limit of SGLD when V is
the loss. Replace ∇V by a learned score and you have a
generative model. Because the score here is exact, the answer can be checked.
Particles collect where e−βV is large and hop
between wells at the Kramers rate, and across 48 bins the empirical measure
sits within a total variation of 1.0×10⁻³ of the
Gibbs law, with a discretization bias of 9×10⁻⁴ on
E[cosX] against the closed form
−I1(β)/I0(β).
Fig. 2
Object
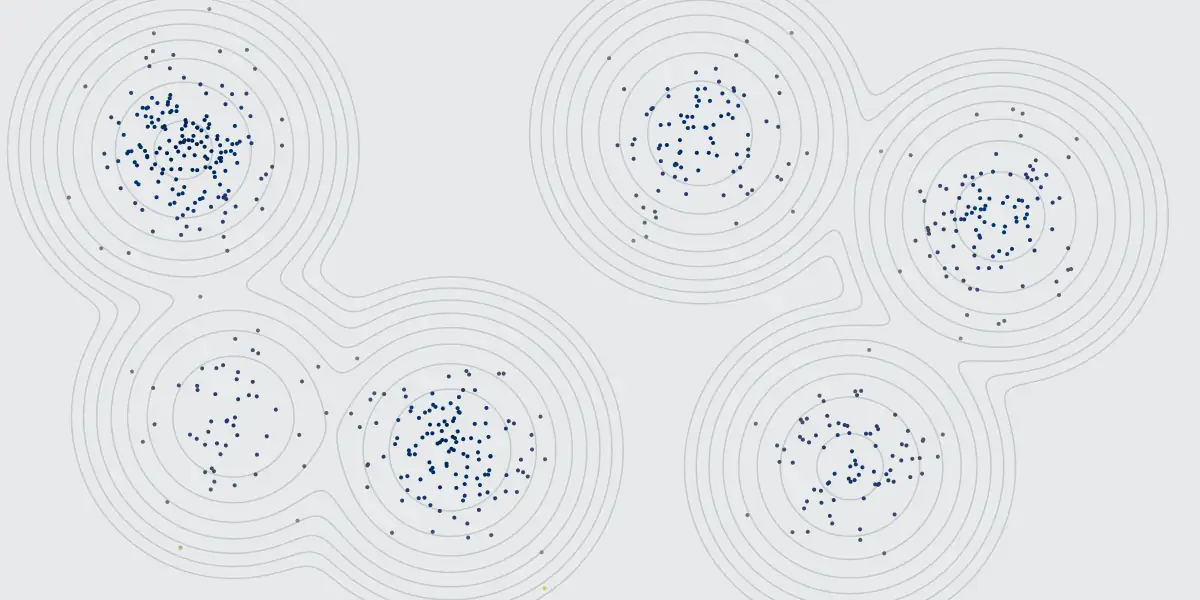
VP-SDE, reverse time
Score
exact, not learned
Steps
320 Euler–Maruyama
Graded on
mode coverage
A diffusion model with an answer key
Generative models are hard to evaluate because the target is unknown, so a
sampler can only be judged on whether its output looks plausible. Make the
target a Gaussian mixture and that changes. The mixture is closed under the
variance-preserving forward kernel, so every marginal pt is
again a mixture and the score ∇logpt is available in
closed form. Anderson's time reversal
dX=[−21β(t)X−β(t)∇logpt(X)]dt+β(t)dWˉ
then runs with an oracle score, so whatever error remains belongs to the
sampler and not to a network. The weights below are deliberately unequal,
which is what makes mode collapse detectable at all. A sampler that drops the
0.08 component still emits individually plausible points, and only the
proportions give it away.
t = 0.00step 320/320max|ŵ−w| = 0.026
Fig. 2. Ancestral sampling from a continuous-time diffusion model. The
forward variance-preserving SDE noises a six-component Gaussian mixture into
𝒩(0, I); the reverse SDE carries 640 samples back over 320
Euler–Maruyama steps. Because a mixture stays a mixture under the VP kernel, the
score used here is exact rather than learned, which leaves discretization as the
only source of error and turns the mixture weights into something gradable. True
weights (0.28, 0.22, 0.17, 0.14, 0.11, 0.08); the readout reports
maxk |ŵk − wk| at the end of
each pass, against a Monte Carlo floor of 0.018 at n = 640. Color and contours
encode −log p₀.
Over 16,384 samples the recovered weights match to
maxk∣w^k−wk∣=0.006 against a Monte Carlo
standard error of 0.0035, the component means to
0.010, and the within-component spread to
0.262 against σ=0.26. This is what
a toy target with a closed form buys you. The sampler either returns the
weights or it does not, and no quantity of plausible-looking output makes up
the difference.
research
Research
Langevin dynamics: sampling, discretization bias, transport coefficients
David Herzog · Mathematics · ongoing
The sampler underneath score-based generative models and stochastic-gradient Langevin dynamics, analyzed where its errors are computable: discretization bias against exact stationary laws, and estimator design for effective diffusivity and mobility.
Large-deviation asymptotics for mean-field interacting systems
Ruoyu Wu · Mathematics · ongoing
Rate functionals and the variational characterization of rare events for the empirical measure of a mean-field particle system. This is the construction that sits one level above the mean-field limit of wide-network training, and the machinery underneath PAC-Bayes.
Stability of neural approximations to evolution equations
Jue Yan · Mathematics · ongoing
Conservation in a cell-average neural network solver is architectural. Stability is not, and the training loss does not separate the networks that survive a long rollout from the ones that come apart. Adapting von Neumann analysis to say which, from the weights alone.
Metastable failures in prefix-cached LLM agent serving
Ali Jannesari · Computer Science · ongoing
An agent re-sends its whole growing conversation every turn, and the serving engine keeps that prefix in a GPU cache so the next turn stays cheap. Under enough concurrent sessions, evictions feed on themselves. Whether a short burst can tip a healthy server into a self-sustaining slow state, and what prevents it, studied by simulation, a queueing model, and real experiments on A100s.
Online calibration of forecasts with early, one-sided feedback
Hongyang Gao · Computer Science · ongoing
A forecast of a cumulative quantity is scored only when its horizon ends, but a miss becomes certain the moment the running sum crosses the bound. A calibration layer that credits those certain misses early and keeps accounts of what is still pending, with its coverage guarantee proved and checked.
Reliability of tool-using agents
Yang Li · Computer Science · ongoing
When an agent stalls, when is restarting it worth more than waiting, and how do you estimate the probability of a failure too rare for direct simulation to reach? Two pilots on real agents, with the direction still being chosen.